Writing
Graph engineering: build better AI workflows with the fake-edge test
updated 2026-10-19
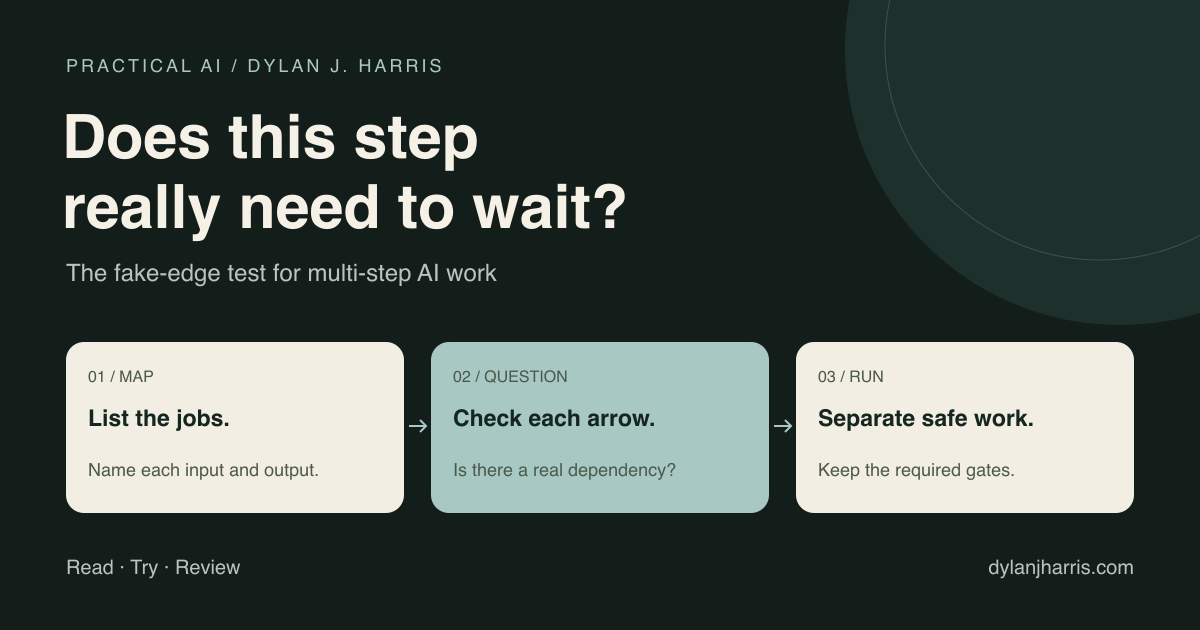
Graph engineering means designing AI workflows as connected jobs rather than one long chat. The fake-edge test asks a simple question at every arrow: does this step actually need the output of the step before it? If not, you can often run those jobs in parallel.
Map where work must wait, where tasks can run together, and who checks each result.
What is in this guide?
- Nodes, edges, and state
- When a graph helps
- The fake-edge test
- A worked research workflow
- Build your first graph
- Tools and frameworks
- Cost and failure handling
- Frequently asked questions
What is an agent graph?
An agent graph maps how work moves from step to step. Nodes do the jobs, edges define what can happen next, and state carries information between them.
A node doesn’t have to be an autonomous agent. It can run a script, call a model, fetch a document, or wrap an agent with its own internal loop. LangChain describes this mix of fixed paths and agent decisions in its graph engineering overview.
| Term | Plain meaning | Example |
|---|---|---|
| Node | A place where work happens | Review a proposed code change |
| Edge | A rule for moving between jobs | Review starts after the change is ready |
| State | Information retained by the workflow | The task, findings, and review status |
| Fan-out | Split work into concurrent jobs | Research three independent questions |
| Fan-in | Collect those results | Combine findings for review |
| Conditional route | Choose a path based on a result | Accept, revise, or stop |
| Human gate | Pause for a person's decision | Approve a refund before sending it |
A knowledge graph maps facts and relationships. An agent graph maps execution. A workflow can query a knowledge graph, but the two solve different problems.
A loop also fits inside a graph. For example, a worker can draft, check, and revise until it meets a stopping rule. You can draw that cycle explicitly or put it inside a node. A graph is not necessarily a DAG: a directed acyclic graph has no cycles.
When should you use an agent graph?
Use a graph when explicit coordination solves a problem you can name.
| Your situation | A sensible starting point |
|---|---|
| One short task with a clear answer | One model call or chat |
| A fixed series of dependent steps | A simple sequential workflow |
| Several independent questions | Parallel workers, then one review |
| Different rules for different inputs | A routing step with defined branches |
| An open-ended investigation | An agent loop with tools and limits |
| A sensitive action | A permission check and approval gate |
Sequential work can still benefit from a graph's checkpoints or routing. It simply does not gain speed from parallel execution. A human approval step also fits inside a graph; it is not a reason to avoid one.
Start with the smallest useful design. Anthropic's guide to effective agents recommends adding complexity only when it improves results. Its distinction between fixed workflows and agents that choose their next steps is useful here.
How does the fake-edge test work?
At each arrow, ask: does job B need a result from job A?
If yes, keep the dependency. If no, check whether the jobs share anything that makes concurrent work unsafe.
| Proposed sequence | What to check | Decision |
|---|---|---|
| Read file A, then read unrelated file B | Both use the same fixed revision | They can usually run together |
| Write a draft, then check its claims | The checker needs the draft | Keep the order |
| Two agents edit the same file | Changes can collide | Split ownership or work in sequence |
| Fetch two independent data sources | API and concurrency limits | Run together within those limits |
| Read an account balance, then issue a refund | Financial state can change | Use controlled transactions and authorization |
An absent data dependency is only the first check. Files, database records, locks, rate limits, and external side effects also matter.
What speed improvement should you expect?
Suppose three independent checks take two, three, and four minutes. Running them in sequence takes nine minutes. Running them together takes about four minutes, plus coordination and merge time.
That is an illustration, not a promised speedup. A rate limit, slow shared tool, or busy machine can erase the gain. More workers can finish sooner while still using more tokens.
What is a fake edge in code review?
This sequence may contain fake dependencies:
Code → Security review → Logic review → Style review → CombineIf every reviewer can inspect the same finished change independently, use:
Code → [Security review, Logic review, Style review] → CombineFreeze the revision under review. If the code changes while checks are running, decide which checks must restart—otherwise you end up combining three reviews of three different commits.
What does a useful research graph look like?
A practical pattern is a diamond: split the question, research independent angles in parallel, and bring the findings back together.
For example: Should I test a bookkeeping product for Shopify merchants?
| Stage | Job | Required input | Output |
|---|---|---|---|
| Plan | Define the decision and research questions | The product idea | A short research brief |
| Research | Study customer problems | The brief | Evidence of recurring problems |
| Research | Study alternatives | The brief | Competitors and substitutes |
| Research | Study distribution | The brief | Ways to reach likely users |
| Review | Challenge material claims | All three findings | Corrections, gaps, and source checks |
| Synthesize | Make a recommendation | Reviewed evidence | Test, pause, or stop, with reasons |
| Decide | Approve the next experiment | The recommendation | A human decision |
Run the three research jobs in parallel, then review their combined evidence before writing the recommendation.
Give workers a shared output format: claim, primary source, date, evidence, and uncertainty. A consistent handoff saves the reviewer from guessing what each worker meant.
Why use a separate reviewer?
A separate review step makes verification a distinct job. Ask the reviewer to look specifically for unsupported claims, contrary evidence, and missing constraints.
A fresh context reduces inherited assumptions, though it doesn’t guarantee independence or accuracy. Two agents running the same model over the same sources can make the exact same mistake. Require evidence outside their agreement: a quoted source passage, a passing test, or a reproduced calculation.
How do you build your first graph?
- Pick one recurring task. Choose work you know well enough to judge.
- Define the output. “A one-page recommendation with sources” is clearer than “research this.”
- List the jobs. State the input, output, owner, and pass condition for each.
- Draw real dependencies. Apply the fake-edge test, then check shared resources.
- Add review and approval. Put gates in front of actions that need authorization.
- Plan for failure. Define timeouts, retry limits, and a clean stop when blocked.
- Run it by hand. Separate chats and a shared folder are enough for a first trial.
- Measure the result. Compare quality, elapsed time, cost, and corrections against your simpler baseline.
My rule of thumb: run the workflow by hand a few times before writing orchestration code. If a process is confusing in a folder of markdown files, a framework will only automate the confusion.
A reusable job brief
Job:
Input and fixed version:
Output file or data shape:
Success conditions:
Sources or tools allowed:
Files or records this job may change:
Time and cost limit:
What to do if blocked:
Keep outputs separate until the merge step. For code changes, assign distinct files or isolated checkouts. For research, one file per question is usually enough.
Which tools can run an agent graph?
Choose the workflow first. Then choose the amount of infrastructure it needs.
| Approach | Useful when | What you must supply |
|---|---|---|
| Separate chats and files | You are testing the workflow | Scheduling, handoffs, and review |
| A small script | The paths are simple and repeatable | State storage, retries, and limits |
| LangGraph | You want explicit workflow patterns and agent steps | Your state, nodes, routes, and tests |
| Microsoft Agent Framework | You want agent and workflow orchestration in Microsoft's framework | Your tools, workflow, deployment, and permissions |
| Google ADK | You want sequential, parallel, or loop workflow agents | Your agents, shared-state rules, and deployment |
This is a starting list, not a popularity ranking or a claim that one framework wins every workload. Read the current documentation before choosing versions or production hosting.
How do you control cost and handle failures?
Track the cost of a successful result, including retries and review. A fast first attempt that needs three repairs may be the expensive option.
Count model usage, tool fees, infrastructure, and human review time. Parallel scheduling alone does not multiply the price of identical calls. Extra calls, repeated context, longer outputs, and retries do.
Use ordinary code for mechanical steps. A script that sorts files needs no model inference, though it still uses compute and may call paid services.
| Failure | Design response |
|---|---|
| A worker times out | Retry a bounded number of times, then report the gap |
| Two outputs conflict | Compare their evidence before choosing one |
| A reviewer requests endless revisions | Set a revision limit and escalate |
| A job repeats an external action | Use an idempotency key or a recorded action status |
| The process restarts | Resume from persisted state, if implemented |
| The final answer is polished but wrong | Check sources and run objective tests |
A diagram does not automatically make a workflow durable. Checkpoints and safe retries need implementation. LangGraph explains these requirements in its persistence guide.
A small preflight checklist
- Each job has a clear input and output.
- Concurrent jobs can run without conflicting writes.
- Reviewers check evidence, not just agreement.
- Retries and revision loops have limits.
- External actions require the right permission.
- You know how to resume or stop after failure.
- The graph improves on the simpler baseline.
Frequently asked questions
Is graph engineering different from prompt engineering?
Prompt engineering shapes an individual request. Graph engineering shapes how jobs depend on one another. A graph can contain prompts, scripts, tools, and agent loops.
Does a graph require multiple agents?
No. A graph can mix ordinary code with one model call or one agent. Multiple agents are useful only when dividing the work helps.
Can I use a graph without code?
Yes. Draw the jobs and dependencies, run separate chats, and pass the results between them. That is a useful way to test the design before automating it.
Do independent jobs always belong in parallel?
No. They may compete for the same file, account, machine, or API limit. Check those constraints after checking whether one job needs the other's output.
Does every agent graph need a loop?
No. Some workflows finish in a fixed series of steps. Add cycles only where retries or revision are useful, and give them a stopping rule.
Where does RAG fit?
Retrieval-augmented generation supplies external information for an answer. A graph can retrieve documents in one node, draft in another, and check citations in a third. See the website assistant guide for that use case.
Sources and further reading
The earlier version of this article grew from Greg Isenberg's graph engineering episode and a post by Anatoli Kopadze. They remain credited as inspiration. The technical guidance above uses the linked framework documentation; the workflow examples are my own illustrations.
Use the model comparison scorecard to test the model inside each job.